 FLUX
Multimodal AI models for image, video, audio, and action prediction — accessible via API or open weights.
Features
- Multimodal generation: video, images, audio, and action prediction in one model
- Up to 20-second video clips with native audio and multilingual speech
- Accurate text rendering and stylistic diversity across generated content
- Simple-to-integrate API for production-scale workloads
- Open weights available for self-hosting and fine-tuning
- FLUX 3 Action for robotics with visual observation and instruction input
- In-browser playground for prompt experimentation
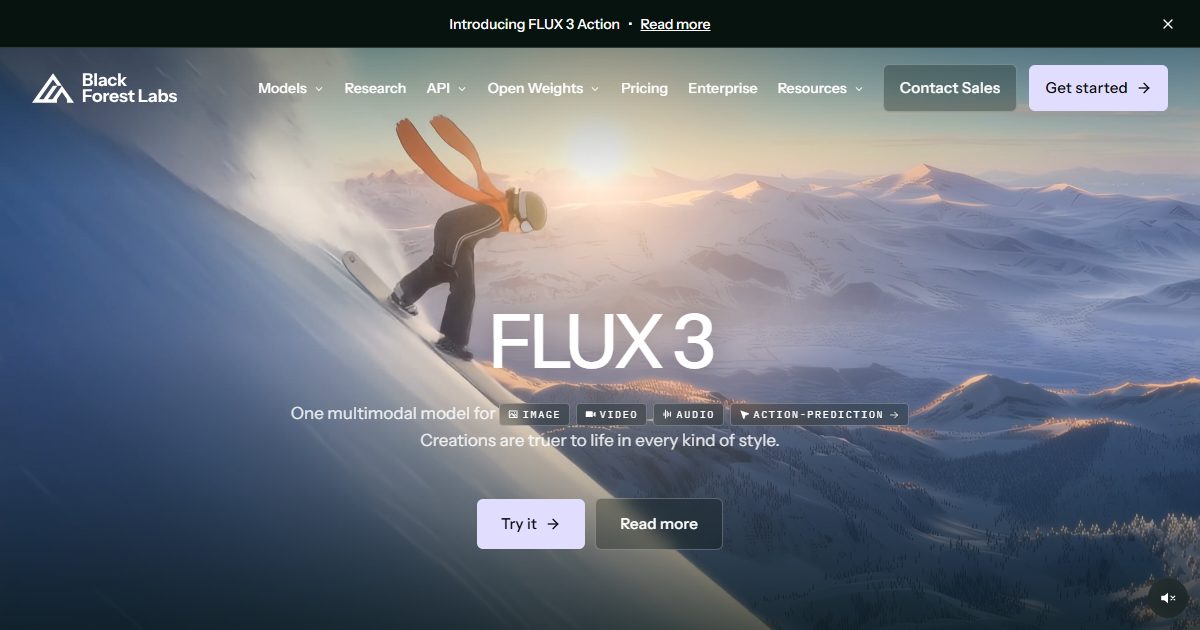
Black Forest Labs builds FLUX, a family of multimodal AI models that understand, reason, and act in the world. FLUX 3 unifies video, image, audio, and action-prediction into a single model, generating up to 20-second clips with native audio from text, images, or keyframes.
Developers can access FLUX through a simple-to-integrate API built for production-scale workloads, or download open weights to run and customize on their own infrastructure. An in-browser playground lets you experiment with prompts before integrating.
FLUX 3 Action is an open-weight 7B world-action model for robotics, taking visual observations and text instructions to predict physical outcomes and robot control actions. It achieved first place on the RoboLab benchmark.